

Summary
ChatGPT was released on November 30, 2022, as a free research preview built on a GPT-3.5 model, according to OpenAI's announcement; developers got the same model through the API on March 1, 2023, at $2 per million tokens. This AI model release timeline covers 159 notable large language models, from OpenAI's GPT-1 (June 11, 2018) to GPT-6.1 Terra (October 26, 2026), with release date, open-weight status, context window, input types and launch API price for each, every row linked to the lab's own announcement, model card or documentation.
The pace has changed most since 2023. The table holds 19 releases from 2023, 35 from 2024, 44 from 2025 and 51 from January through October 2026. Context windows grew from 512 tokens for GPT-1 to about 1 million tokens for 39 of the 51 models released in 2026, and the price of a top OpenAI model fell from $30 per million input tokens for GPT-4 in March 2023 to $2 for GPT-6.1 Sol in September 2026. Of the 159 rows, 82 are open-weight releases, led by Meta, Mistral, DeepSeek, Alibaba's Qwen team and Moonshot AI.
The table is sortable and downloadable as CSV or JSON. Release date means the first day the model was publicly usable (in an app, through an API, or as downloadable weights), not the day a paper or teaser appeared. Prices are the lab's standard list price per million tokens on launch day; a dash means the lab did not sell API access or did not publish a price.
Key Findings
- OpenAI released ChatGPT on November 30, 2022, as a free research preview based on a GPT-3.5 model fine-tuned with reinforcement learning from human feedback. (OpenAI: Introducing ChatGPT)
- GPT-4 launched on March 14, 2023, with an 8,192-token context window at $0.03 per 1,000 prompt tokens and $0.06 per 1,000 completion tokens ($30 and $60 per million), according to OpenAI. (OpenAI: GPT-4)
- Google's Gemini 1.5 Pro became the first model offered through a public API with a 1-million-token context window when it entered public preview in the Gemini API on April 9, 2024. (Google Developers Blog: Gemini 1.5 Pro now available in 180+ countries)
- DeepSeek released the open-weight reasoning model DeepSeek-R1 under the MIT License on January 20, 2025, with API prices of $0.55 per million input tokens (cache miss) and $2.19 per million output tokens. (DeepSeek-R1 Release (DeepSeek API news, archived copy))
- Meta released Llama 4 Scout on April 5, 2025, with a 10-million-token context window, the longest of any model in this dataset. (The Llama 4 herd (Meta AI))
- OpenAI's gpt-oss-120b and gpt-oss-20b, released on August 5, 2025, under the Apache 2.0 license, were the company's first open-weight language models since GPT-2 in 2019. (OpenAI: Introducing gpt-oss)
- Anthropic cut the price of its Opus tier from $15 and $75 per million input and output tokens to $5 and $25 with Claude Opus 4.5 on November 24, 2025. (Anthropic: Introducing Claude Opus 4.5)
- OpenAI released GPT-6 Astra on September 3, 2026, and GPT-6 Sol and GPT-6 Luna on September 22, 2026, with Luna priced at $0.10 per million input tokens and $0.50 per million output tokens, according to its API changelog. (OpenAI API changelog)
- Anthropic released Claude Opus 5.5 on September 22, 2026, with a 1-million-token context window at $4 per million input tokens and $20 per million output tokens, 20% below Claude Opus 5. (Anthropic: Claude Opus 5.5)
- Moonshot AI's Kimi K3, released on July 16, 2026, is a 2.8-trillion-parameter mixture-of-experts model whose weights Moonshot published under its own Kimi K3 License, with API prices of $3 and $15 per million input and output tokens. (Kimi K3: Open Frontier Intelligence (Moonshot AI))
Figures
Figure 1
Notable LLM releases per year, open vs closed weights
Count of releases in this dataset by year of public availability
Releases tracked here rose from 4 in 2022 to 51 in 2026 (January to October), and 82 of the 159 models shipped with open weights.
Source: agitracker.io analysis of 159 records in this dataset. Download PNG
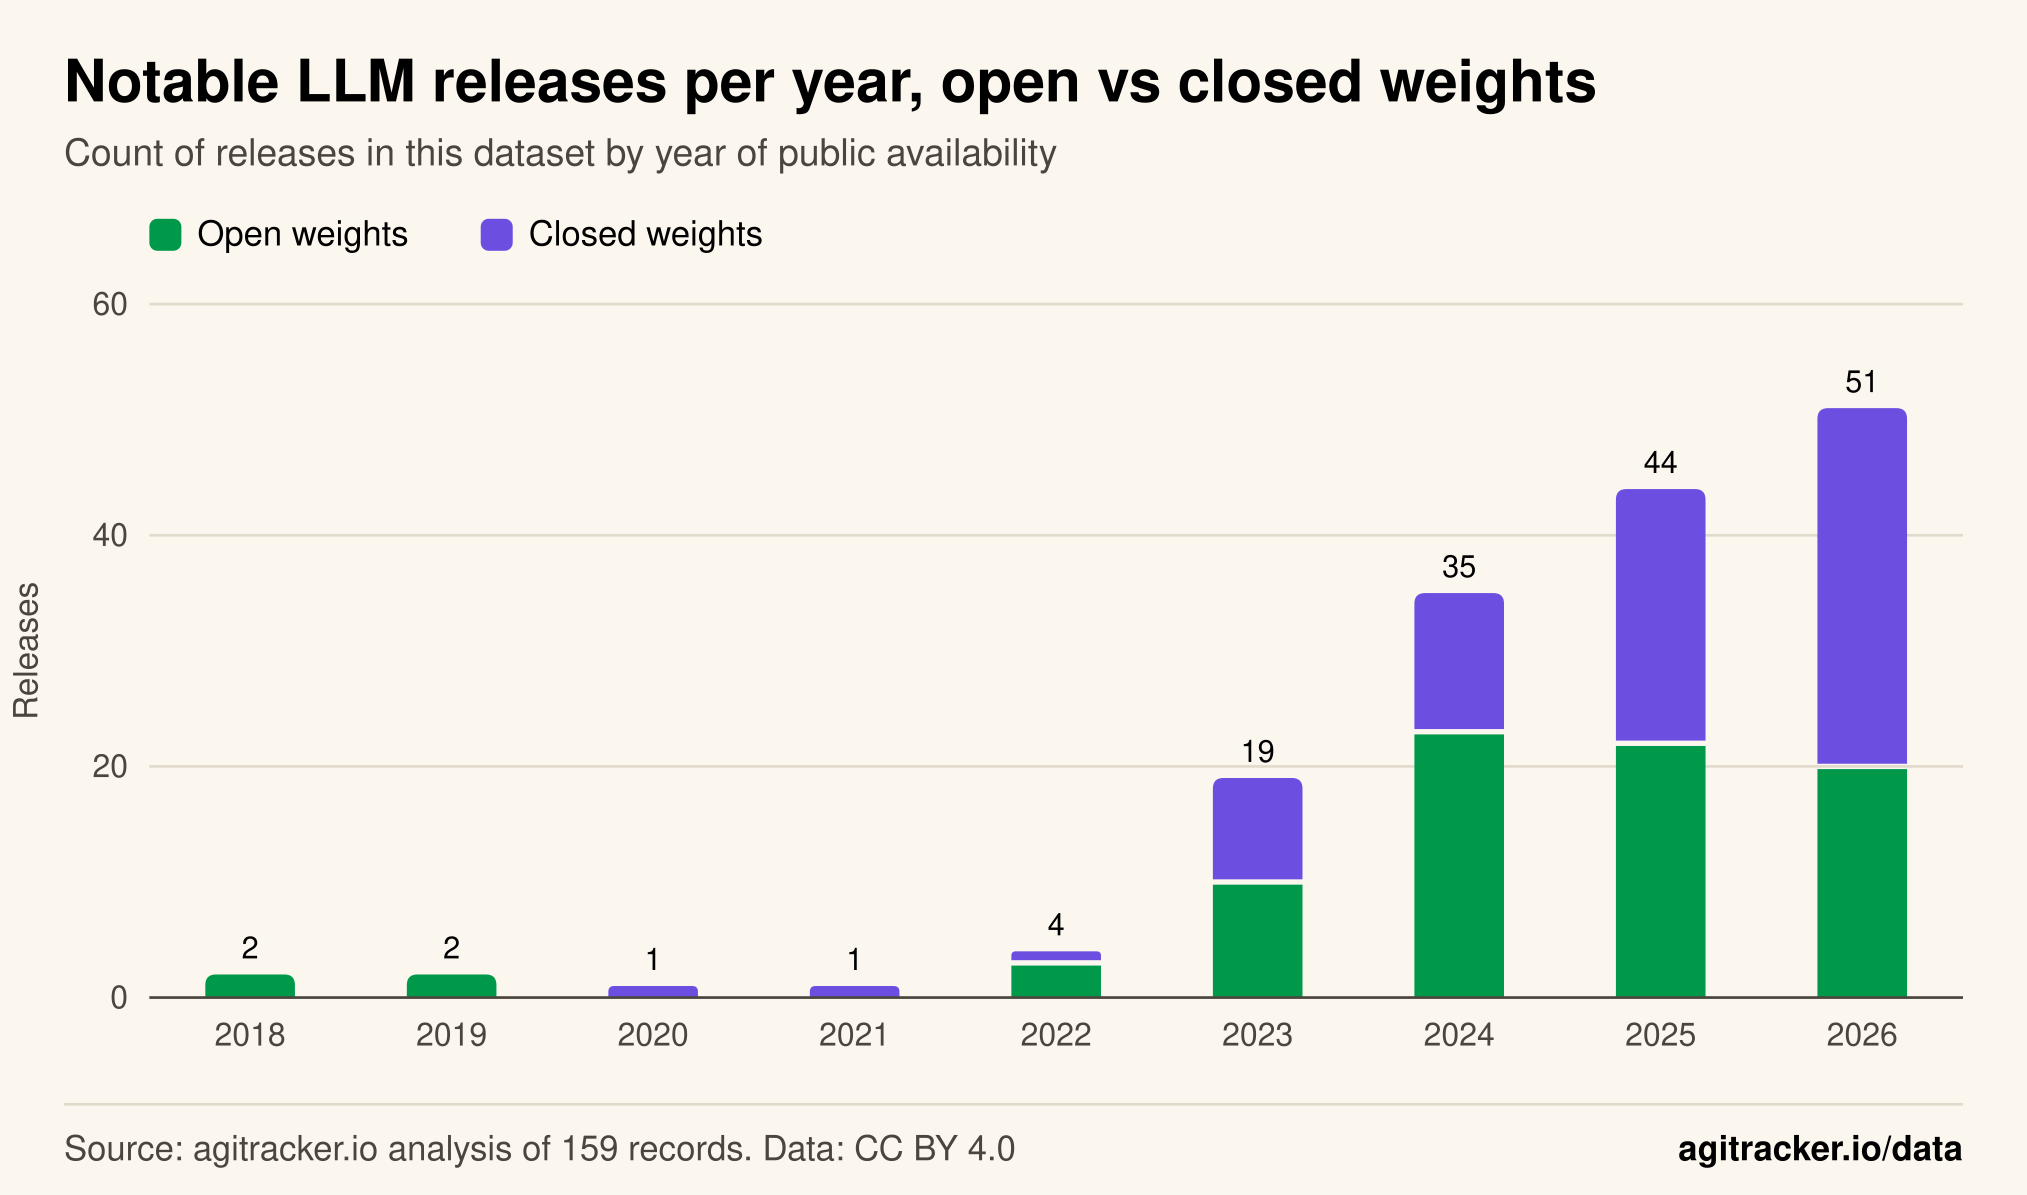
Figure 2
Context window at launch, by release date
Maximum context in tokens, log scale
Maximum context grew from 512 tokens with GPT-1 to 10 million with Llama 4 Scout, with the largest jumps in 2023 and 2024.
Source: agitracker.io analysis of 159 records in this dataset. Download PNG
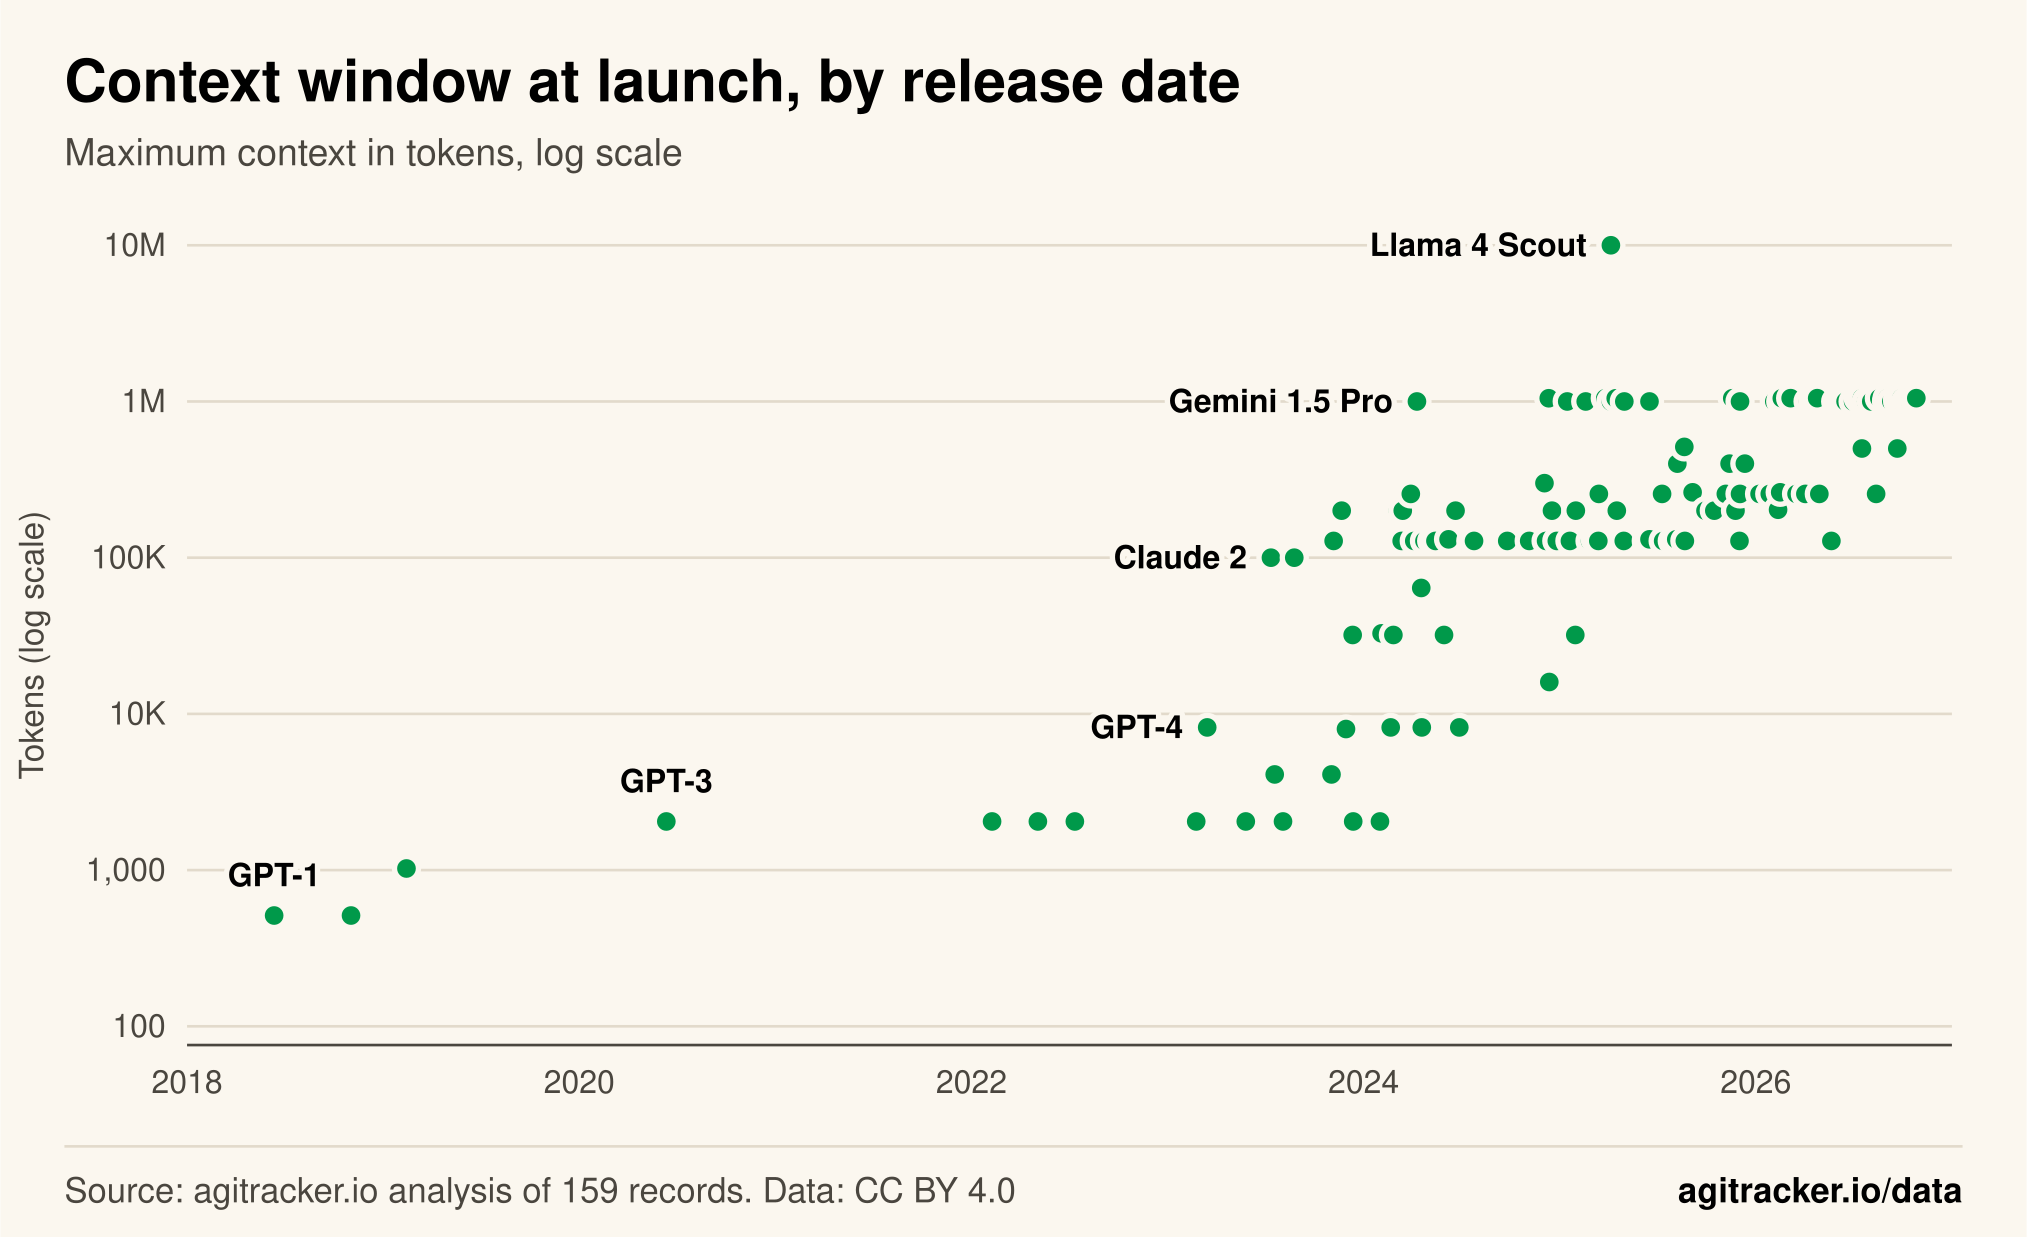
Figure 3
API input price at launch, by release date
US$ per million input tokens, log scale (models with a published launch price)
In 2025 and 2026, launch prices ran from $0.10 per million input tokens (Claude Haiku 5.5, GPT-6 Luna) to $75 (GPT-4.5).
Source: agitracker.io analysis of 159 records in this dataset. Download PNG
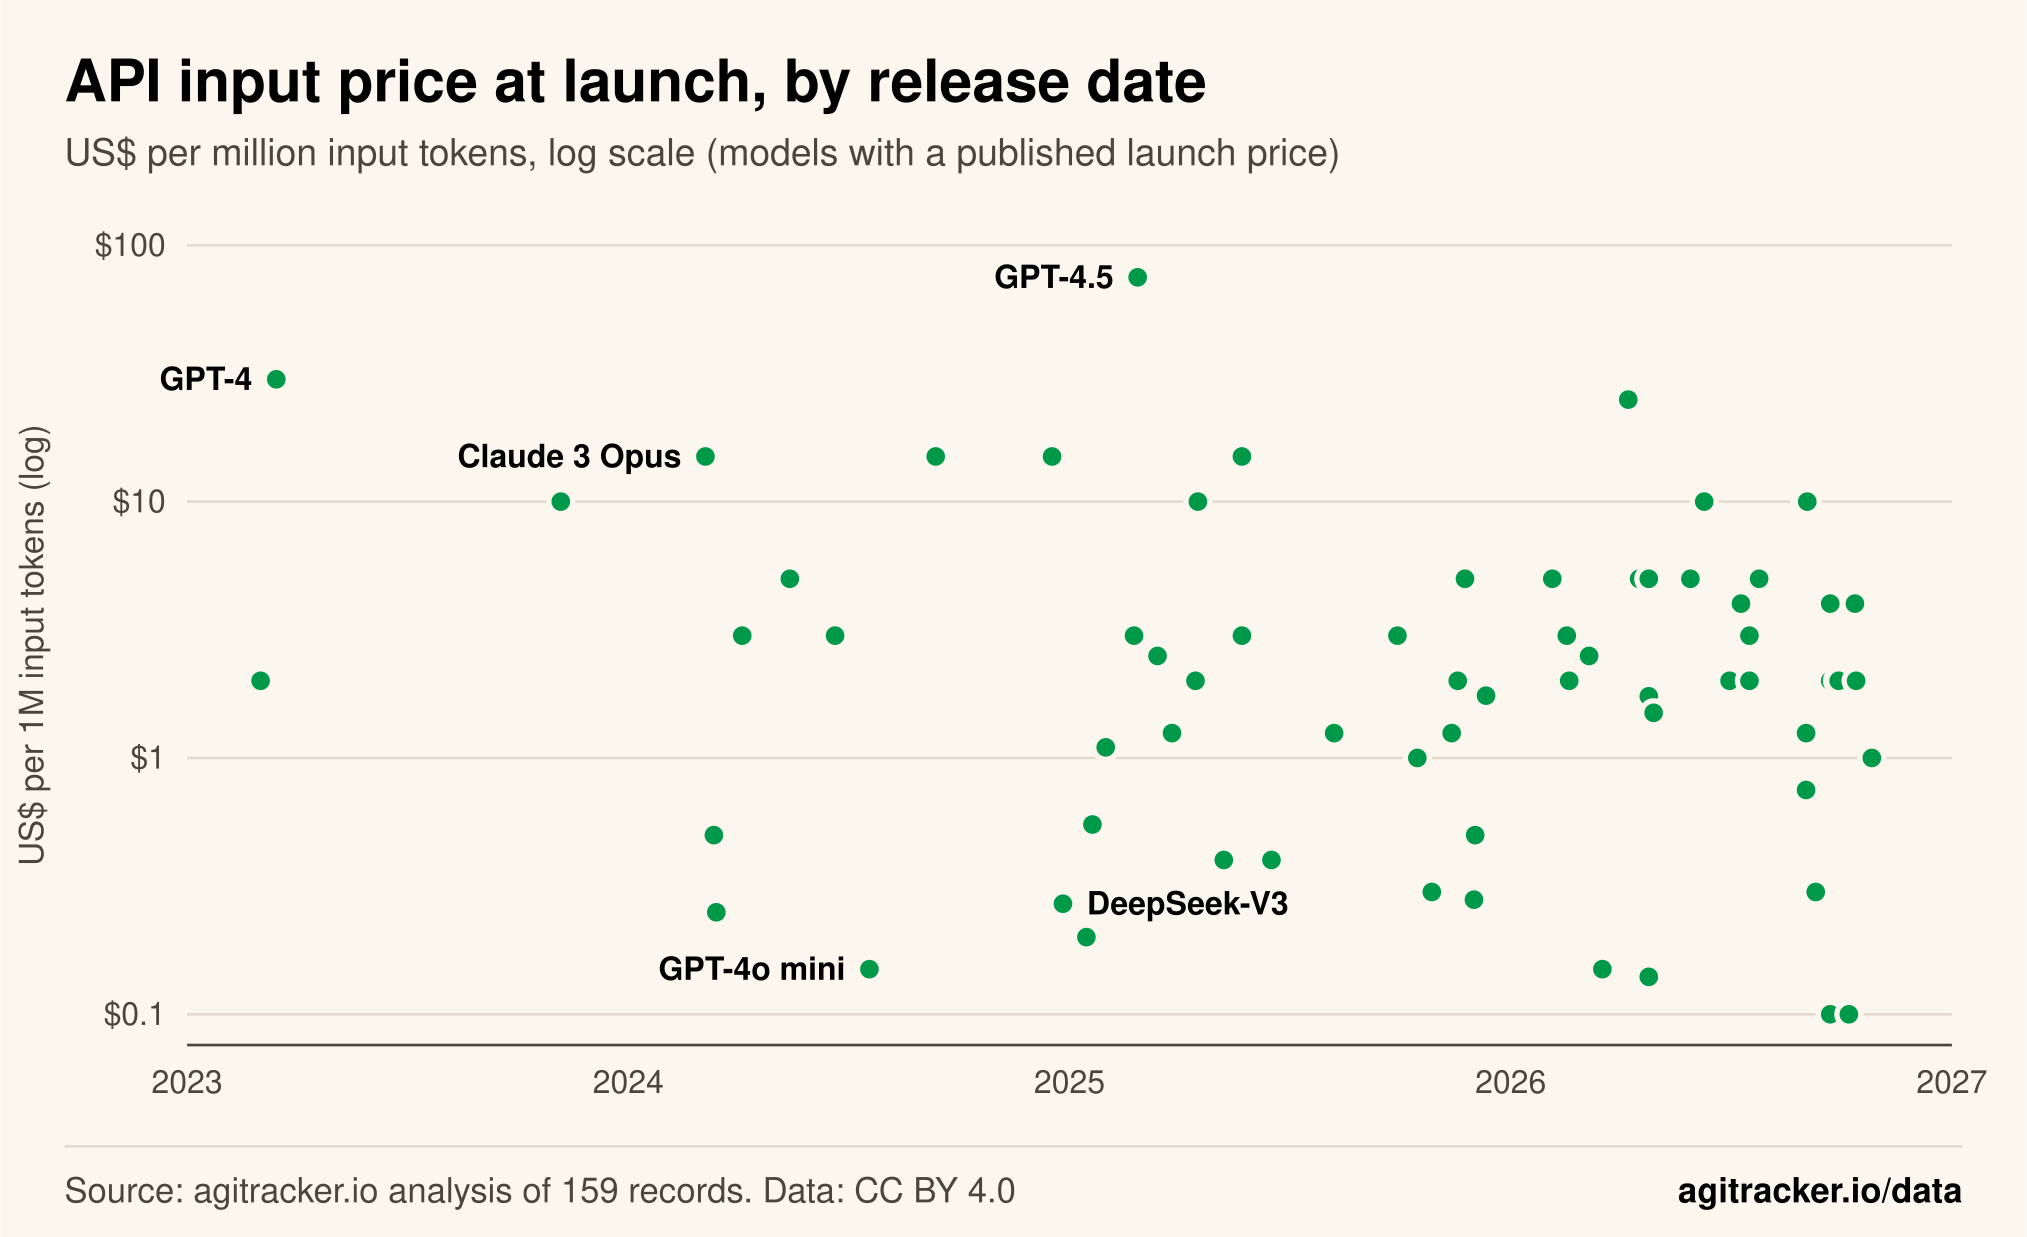
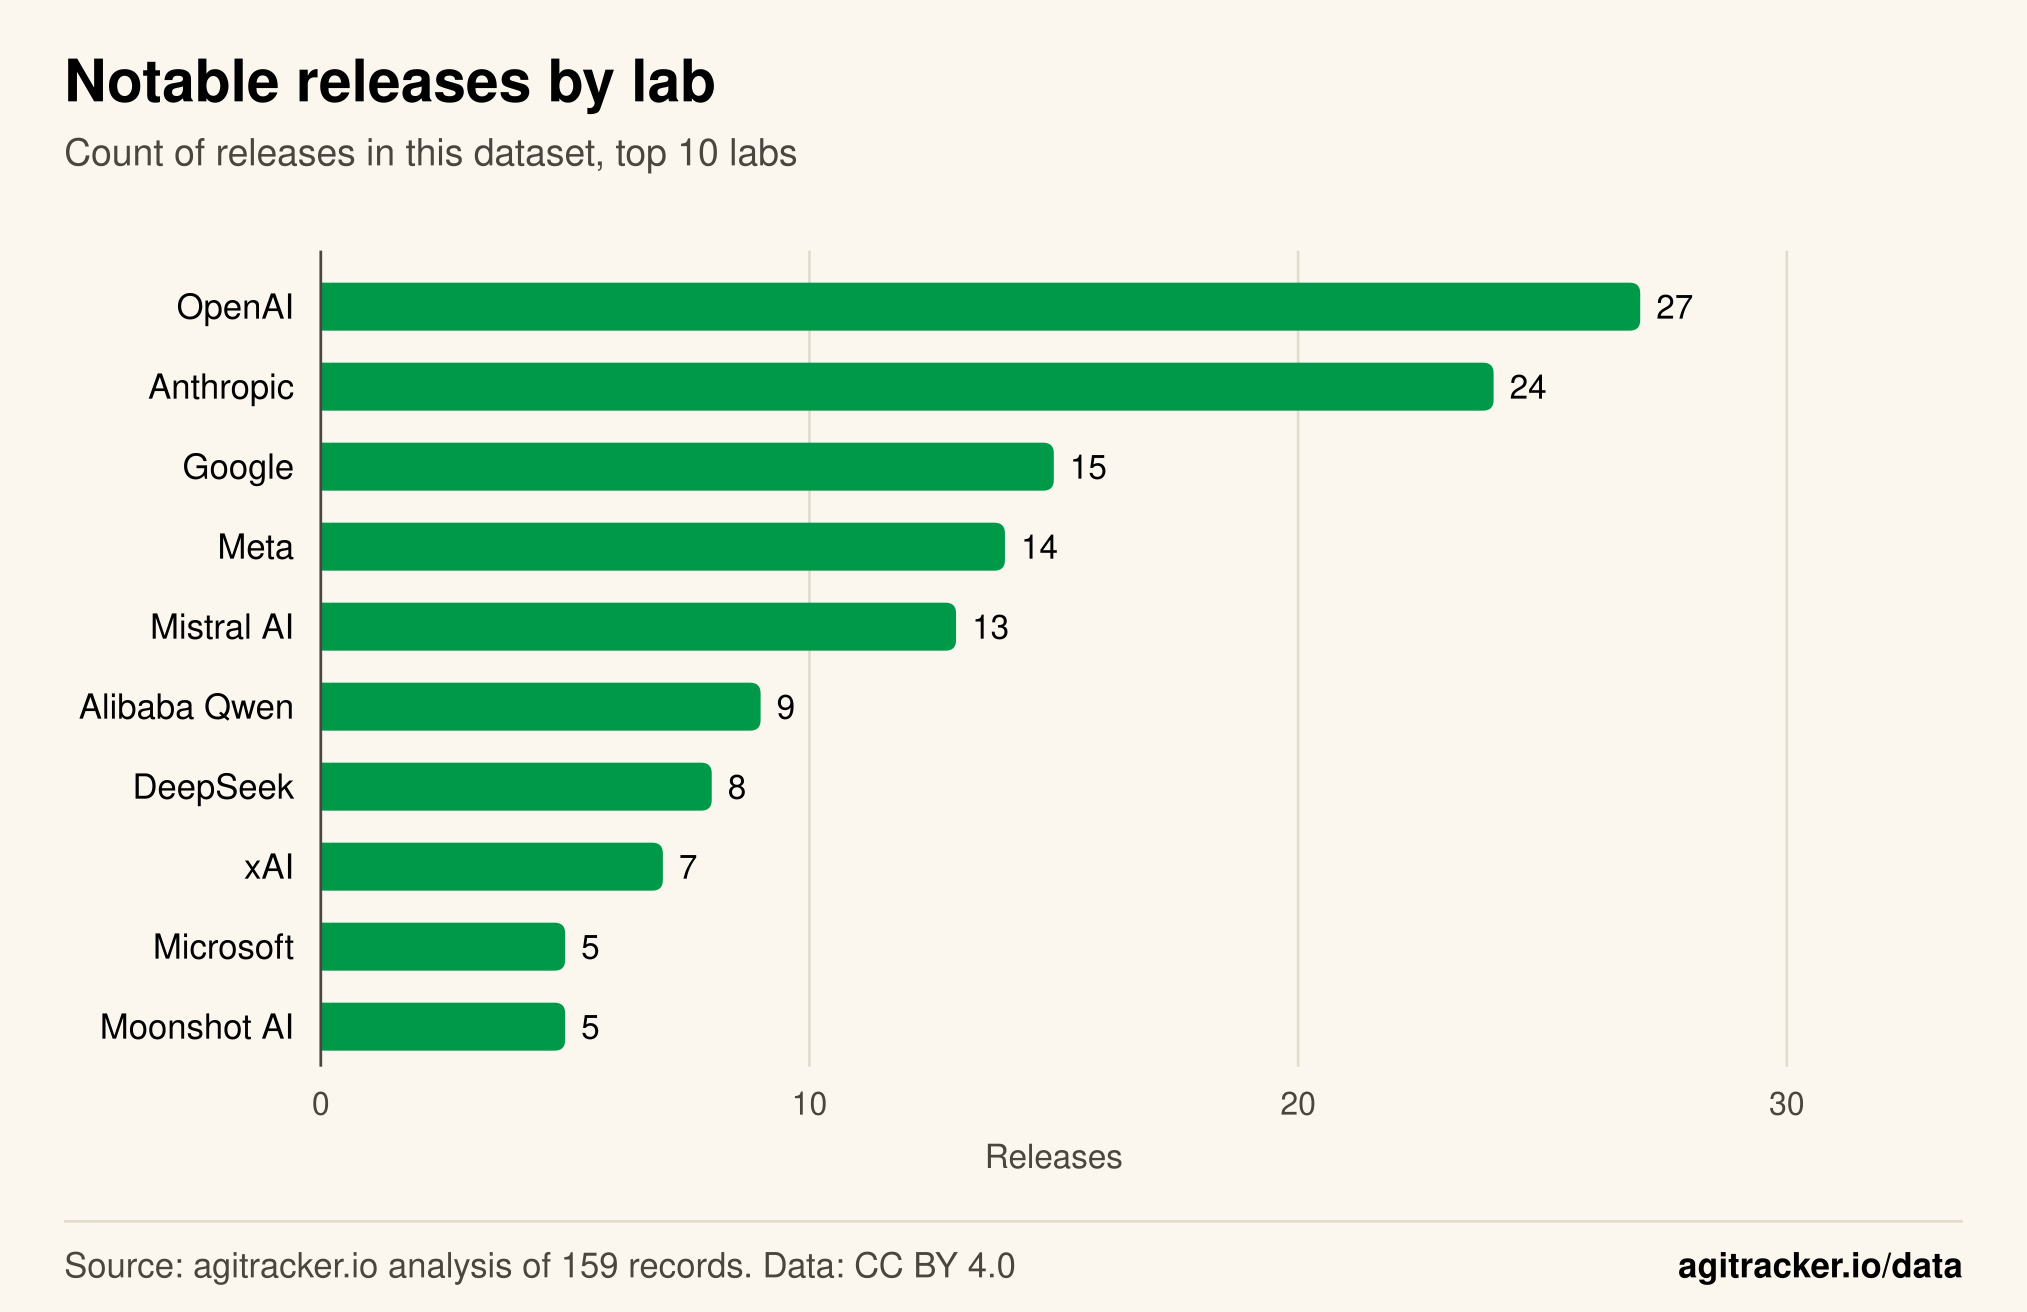
Figure 4
Notable releases by lab
Count of releases in this dataset, top 10 labs
OpenAI and Anthropic account for the most releases tracked here, followed by Google and Meta.
Source: agitracker.io analysis of 159 records in this dataset. Download PNG
Major AI model releases, 2018 to October 2026
| First public availability (app, API or weights) | Yes = weights downloadable, under any license | Tokens at launch; max sequence length for early models | USD per 1M tokens, lab's own API, standard list price at launch | USD per 1M tokens, lab's own API, standard list price at launch | Source | ||||
|---|---|---|---|---|---|---|---|---|---|
| GPT-1 | OpenAI | 2018-06-11 | Yes | 512 | Text | — | — | First GPT model: generative pre-training of a Transformer followed by fine-tuning | OpenAI: Improving language understanding with unsupervised learning |
| BERT | 2018-11-02 | Yes | 512 | Text | — | — | Bidirectional transformer encoder; Google open-sourced code and pre-trained models | Google Research blog: Open Sourcing BERT | |
| GPT-2 | OpenAI | 2019-02-14 | Yes | 1024 | Text | — | — | Staged release: only a smaller model at first; full 1.5B-parameter weights published 2019-11-05 | OpenAI: Better language models and their implications |
| T5 | 2019-10-23 | Yes | — | Text | — | — | Text-to-text framework; largest model 11B parameters; released with the C4 dataset | arXiv: Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer | |
| GPT-3 | OpenAI | 2020-06-11 | No | 2048 | Text | — | — | 175 billion parameters; first OpenAI model sold through an API (private beta) | OpenAI: OpenAI API |
| Jurassic-1 Jumbo | AI21 Labs | 2021-08 | No | — | Text | — | — | 178B parameters; offered through the AI21 Studio open beta API | AI21 Labs: Announcing AI21 Studio and Jurassic-1 |
| GPT-NeoX-20B | EleutherAI | 2022-02-09 | Yes | 2048 | Text | — | — | 20B parameters; weights released under Apache 2.0 after a one-week delay from the Feb 2 announcement. | Announcing GPT-NeoX-20B (EleutherAI blog) |
| OPT-175B | Meta | 2022-05-03 | Yes | 2048 | Text | — | — | 175B parameters; weights by request under a noncommercial research license (OPT-175B License). | Democratizing access to large-scale language models with OPT-175B (Meta AI) |
| BLOOM | BigScience | 2022-07-11 | Yes | 2048 | Text | — | — | 176B-parameter multilingual model built by a 1,000+ researcher collaboration; BigScience RAIL License v1.0. | bigscience/bloom model card (Hugging Face) |
| ChatGPT (GPT-3.5) | OpenAI | 2022-11-30 | No | — | Text | — | — | Free research preview of a chat interface trained with RLHF; no API until March 2023 | OpenAI: Introducing ChatGPT |
| LLaMA | Meta | 2023-02-24 | Yes | 2048 | Text | — | — | 7B to 65B parameters; weights granted case by case under a noncommercial research license. | Introducing LLaMA: A foundational, 65-billion-parameter large language model (Meta AI) |
| GPT-3.5 Turbo (ChatGPT API) | OpenAI | 2023-03-01 | No | — | Text | 2 | 2 | Same model as ChatGPT; priced at $0.002 per 1K tokens, 10x cheaper than earlier GPT-3.5 models | OpenAI: Introducing ChatGPT and Whisper APIs |
| Claude | Anthropic | 2023-03-14 | No | — | Text | — | — | First Claude release, alongside the lighter Claude Instant; offered via chat interface and API | Anthropic: Introducing Claude |
| GPT-4 | OpenAI | 2023-03-14 | No | 8192 | Text | 30 | 60 | 32,768-token gpt-4-32k variant at $60/$120; image input demonstrated but not in the API at launch | OpenAI: GPT-4 |
| PaLM 2 | 2023-05-10 | No | — | Text | — | — | Announced at Google I/O in four sizes (Gecko, Otter, Bison, Unicorn); powered Bard and 25+ Google products | Google: Introducing PaLM 2 | |
| Falcon 40B | TII (UAE) | 2023-05-25 | Yes | 2048 | Text | — | — | 40B parameters trained on 1 trillion tokens; made royalty-free under Apache 2.0 on May 31, 2023. | UAE's TII Launches Open-Source Falcon 40B (TII) |
| Claude 2 | Anthropic | 2023-07-11 | No | 100000 | Text | — | — | 100K-token prompts; launched public beta of claude.ai in the US and UK | Anthropic: Claude 2 |
| Llama 2 | Meta | 2023-07-18 | Yes | 4096 | Text | — | — | 7B to 70B; first Llama licensed for commercial use (Llama 2 Community License), launched with Microsoft. | Meta and Microsoft Introduce the Next Generation of Llama (Meta AI) |
| Qwen-7B | Alibaba Qwen | 2023-08-03 | Yes | 2048 | Text | — | — | First open-weight Qwen model, released with Qwen-7B-Chat under the Tongyi Qianwen license; context later extended to 8K in a Sept 2023 update. | Qwen GitHub README (news and updates) |
| Code Llama | Meta | 2023-08-24 | Yes | 100000 | Text | — | — | Code-specialized Llama 2; trained on 16K-token sequences, stable up to 100K tokens; 70B version followed Jan 29, 2024. | Introducing Code Llama (Meta AI) |
| Falcon 180B | TII (UAE) | 2023-09-06 | Yes | — | Text | — | — | 180B parameters trained on 3.5 trillion tokens; Falcon 180B TII License based on Apache 2.0. | TII Introduces World's Most Powerful Open LLM: Falcon 180B (TII) |
| Mistral 7B | Mistral AI | 2023-09-27 | Yes | — | Text | — | — | Mistral's first model; Apache 2.0, uses sliding window attention. | Mistral 7B (Mistral AI) |
| Yi-34B | 01.AI | 2023-11-02 | Yes | 4096 | Text | — | — | 34B dense model; a 200K-context variant (Yi-34B-200K) followed on 2023-11-05. Model card now lists Apache 2.0. | Yi-34B model card (01.AI, Hugging Face) |
| GPT-4 Turbo | OpenAI | 2023-11-06 | No | 128000 | Text, Image | 10 | 30 | First OpenAI model with a 128K context window; launched as a preview at DevDay | OpenAI: New models and developer products announced at DevDay |
| Claude 2.1 | Anthropic | 2023-11-21 | No | 200000 | Text | — | — | Doubled context to 200K tokens; added system prompts and tool use in beta | Anthropic: Introducing Claude 2.1 |
| Amazon Titan Text Express | Amazon | 2023-11-29 | No | 8000 | Text | — | — | Generally available on Amazon Bedrock with Titan Text Lite (4,000 tokens) | AWS What's New: Amazon Titan Text models Express and Lite now generally available |
| Gemini 1.0 Pro | 2023-12-06 | No | 32000 | Text | — | — | First Gemini model; Bard switched to Gemini Pro on launch day; API access from December 13 with a 32K context window; a separate Pro Vision endpoint accepted images | Google: Introducing Gemini | |
| Mixtral 8x7B | Mistral AI | 2023-12-11 | Yes | 32000 | Text | — | — | Sparse mixture-of-experts model with open weights under Apache 2.0. | Mixtral of experts (Mistral AI) |
| Phi-2 | Microsoft | 2023-12-12 | Yes | 2048 | Text | — | — | 2.7B-parameter small language model; MIT license | Microsoft Research: Phi-2: The surprising power of small language models |
| OLMo 7B | Ai2 | 2024-02-01 | Yes | 2048 | Text | — | — | Released weights plus full training data, code, logs and checkpoints under Apache 2.0. | OLMo: Open Language Model (Ai2) |
| Qwen1.5 | Alibaba Qwen | 2024-02-04 | Yes | 32768 | Text | — | — | Family from 0.5B to 72B (later 110B); all sizes support a 32,768-token context. | Introducing Qwen1.5 (Qwen blog) |
| Gemma | 2024-02-21 | Yes | 8192 | Text | — | — | Google's first open-weight Gemma models (2B and 7B) | Google: Gemma, introducing new state-of-the-art open models | |
| Mistral Large | Mistral AI | 2024-02-26 | No | 32000 | Text | — | — | Closed flagship model offered through Mistral's API. | Au Large (Mistral AI) |
| Claude 3 Opus | Anthropic | 2024-03-04 | No | 200000 | Text, Image | 15 | 75 | Claude 3 family launch (Opus, Sonnet); first Claude models with image input | Anthropic: Introducing the next generation of Claude |
| Command R | Cohere | 2024-03-11 | Yes | 128000 | Text | 0.5 | 1.5 | RAG- and tool-use-focused model; weights published under a non-commercial CC-BY-NC license | Cohere docs: Command R |
| Claude 3 Haiku | Anthropic | 2024-03-13 | No | 200000 | Text, Image | 0.25 | 1.25 | Smallest Claude 3 model | Anthropic: Claude 3 Haiku |
| Grok-1 (open weights) | xAI | 2024-03-17 | Yes | — | Text | — | — | 314B-parameter mixture-of-experts base model; weights and architecture released under Apache 2.0. | Open Release of Grok-1 (xAI) |
| Jamba | AI21 Labs | 2024-03-28 | Yes | 256000 | Text | — | — | Hybrid Mamba-Transformer mixture-of-experts model (52B total, 12B active); Apache 2.0 weights | AI21 Labs: Introducing Jamba |
| Command R+ | Cohere | 2024-04-04 | Yes | 128000 | Text | 3 | 15 | Larger RAG model, first available on Microsoft Azure; CC-BY-NC weights | Cohere: Introducing Command R+ |
| Gemini 1.5 Pro | 2024-04-09 | No | 1000000 | Text, Image, Audio, Video | — | — | First public API model with a 1M-token context window; announced February 15, 2024 for limited testing | Google Developers Blog: Gemini 1.5 Pro now available in 180+ countries | |
| Mixtral 8x22B | Mistral AI | 2024-04-17 | Yes | 64000 | Text | — | — | Sparse mixture-of-experts; Apache 2.0. | Cheaper, Better, Faster, Stronger (Mistral AI) |
| Llama 3 | Meta | 2024-04-18 | Yes | 8192 | Text | — | — | 8B and 70B; trained on 8,192-token sequences with a new 128K-vocabulary tokenizer. | Introducing Meta Llama 3 (Meta AI) |
| Phi-3-mini | Microsoft | 2024-04-23 | Yes | 128000 | Text | — | — | 3.8B parameters; 4K and 128K context variants; Microsoft says first model in its class with a 128K window | Microsoft Azure Blog: Introducing Phi-3 |
| DeepSeek-V2 | DeepSeek | 2024-05-06 | Yes | 128000 | Text | — | — | Mixture-of-experts model with 236B total and 21B active parameters; introduced Multi-head Latent Attention. DeepSeek Model License (commercial use allowed). | DeepSeek-V2 GitHub README |
| GPT-4o | OpenAI | 2024-05-13 | No | 128000 | Text, Image | 5 | 15 | 'Omni' model; API launched with text and vision, audio added later | OpenAI API changelog (May 13, 2024) |
| Codestral | Mistral AI | 2024-05-29 | Yes | 32000 | Text | — | — | Mistral's first code model, 22B; Mistral AI Non-Production License. | Codestral (Mistral AI) |
| Qwen2 | Alibaba Qwen | 2024-06-07 | Yes | 131072 | Text | — | — | Sizes 0.5B to 72B; Qwen2-72B kept the Qianwen license while smaller models moved to Apache 2.0. | Hello Qwen2 (Qwen blog) |
| Nemotron-4 340B | NVIDIA | 2024-06-14 | Yes | — | Text | — | — | Family of open models aimed at synthetic data generation; NVIDIA Open Model License. | NVIDIA Releases Open Synthetic Data Generation Pipeline (NVIDIA blog) |
| Claude 3.5 Sonnet | Anthropic | 2024-06-20 | No | 200000 | Text, Image | 3 | 15 | Introduced Artifacts in claude.ai; upgraded version in October 2024 added computer use in beta | Anthropic: Introducing Claude 3.5 Sonnet |
| Gemma 2 | 2024-06-27 | Yes | 8192 | Text | — | — | 9B and 27B open models | Google: Gemma 2 is now available to researchers and developers | |
| GPT-4o mini | OpenAI | 2024-07-18 | No | 128000 | Text, Image | 0.15 | 0.6 | Small, low-cost model that replaced GPT-3.5 Turbo as the cheap default | OpenAI API changelog (Jul 18, 2024) |
| Llama 3.1 405B | Meta | 2024-07-23 | Yes | 128000 | Text | — | — | Meta called the 405B model the first frontier-level open source AI model; 128K context, eight languages. | Introducing Llama 3.1: Our most capable models to date (Meta AI) |
| Mistral Large 2 | Mistral AI | 2024-07-24 | Yes | 128000 | Text | — | — | 123B parameters; weights under the Mistral Research License (non-commercial). | Large Enough (Mistral AI) |
| Grok-2 | xAI | 2024-08-13 | No | — | Text, Image | — | — | Released in beta on X with Grok-2 mini; text and vision understanding. | Grok-2 Beta Release (xAI) |
| o1-preview | OpenAI | 2024-09-12 | No | 128000 | Text | 15 | 60 | First OpenAI reasoning model trained with reinforcement learning to think before answering | OpenAI API changelog (Sep 12, 2024) |
| Qwen2.5 | Alibaba Qwen | 2024-09-19 | Yes | 131072 | Text | — | — | Sizes 0.5B to 72B; most under Apache 2.0, with the 3B and 72B models under Qwen licenses. | Qwen2.5: A Party of Foundation Models! (Qwen blog) |
| Llama 3.2 Vision (11B, 90B) | Meta | 2024-09-25 | Yes | 128000 | Text, Image | — | — | First Llama models with image input; released alongside 1B and 3B text models for devices. | Llama 3.2: edge AI and vision with open, customizable models (Meta AI) |
| Hunyuan-Large | Tencent | 2024-11-05 | Yes | 128000 | Text | — | — | MoE with 389B total and 52B active parameters; Tencent described it as the largest open Transformer MoE at release. Instruct model 128K, pretrain 256K. | Tencent-Hunyuan-Large GitHub README |
| Amazon Nova Pro | Amazon | 2024-12-03 | No | 300000 | Text, Image, Video | — | — | Launched with Nova Micro (text-only, 128K) and Nova Lite (300K) on Amazon Bedrock | AWS News Blog: Introducing Amazon Nova foundation models |
| Llama 3.3 70B | Meta | 2024-12-06 | Yes | 128000 | Text | — | — | Text-only 70B model; Llama 3.3 Community License. | meta-llama/Llama-3.3-70B-Instruct model card (Hugging Face) |
| Gemini 2.0 Flash | 2024-12-11 | No | 1048576 | Text, Image, Audio, Video | — | — | Experimental release December 11, 2024; generally available February 5, 2025 | Google: Introducing Gemini 2.0 | |
| Phi-4 | Microsoft | 2024-12-12 | Yes | 16000 | Text | — | — | 14B-parameter small model focused on math reasoning; MIT license | Microsoft Foundry Blog: Introducing Phi-4 |
| o1 | OpenAI | 2024-12-17 | No | 200000 | Text, Image | 15 | 60 | Full o1 in the API with reasoning_effort control and image input | OpenAI API changelog (Dec 17, 2024) |
| DeepSeek-V3 | DeepSeek | 2024-12-26 | Yes | 128000 | Text | 0.27 | 1.1 | MoE with 671B total and 37B active parameters, trained on 14.8T tokens. Listed price applied from 2025-02-08; V2 prices applied until then. | Introducing DeepSeek-V3 (DeepSeek API news) |
| MiniMax-01 (MiniMax-Text-01) | MiniMax | 2025-01-15 | Yes | 1000000 | Text | 0.2 | 1.1 | MoE with 456B total and 45.9B active parameters using lightning (linear) attention; MiniMax says it handles up to 4M tokens at inference. | MiniMax-01 is Now Open-Source (MiniMax news) |
| DeepSeek-R1 | DeepSeek | 2025-01-20 | Yes | 128000 | Text | 0.55 | 2.19 | Open-weight reasoning model trained with large-scale RL, released under MIT with six distilled smaller models; DeepSeek reported o1-level math, code and reasoning. | DeepSeek-R1 Release (DeepSeek API news, archived copy) |
| Mistral Small 3 | Mistral AI | 2025-01-30 | Yes | 32000 | Text | — | — | 24B latency-optimized model; Apache 2.0. | Mistral Small 3 (Mistral AI) |
| o3-mini | OpenAI | 2025-01-31 | No | 200000 | Text | 1.1 | 4.4 | Small reasoning model for science, math and coding | OpenAI API changelog (Jan 31, 2025) |
| Grok 3 | xAI | 2025-02-19 | No | 1000000 | Text, Image | — | — | xAI says context is 8x its previous models; added Think reasoning mode and DeepSearch. | Grok 3 Beta: The Age of Reasoning Agents (xAI) |
| Claude 3.7 Sonnet | Anthropic | 2025-02-24 | No | — | Text, Image | 3 | 15 | Anthropic calls it the first hybrid reasoning model on the market (instant or extended thinking); launched with Claude Code preview | Anthropic: Claude 3.7 Sonnet and Claude Code |
| GPT-4.5 | OpenAI | 2025-02-27 | No | 128000 | Text, Image | 75 | 150 | Research preview; OpenAI's largest chat model at the time and its most expensive per token; deprecated in April 2025 | OpenAI API changelog (Feb 27, 2025) |
| QwQ-32B | Alibaba Qwen | 2025-03-06 | Yes | 131072 | Text | — | — | 32B dense reasoning model trained with reinforcement learning, Apache 2.0. | QwQ-32B: Embracing the Power of Reinforcement Learning (Qwen blog) |
| Gemma 3 | 2025-03-12 | Yes | 128000 | Text, Image | — | — | Open models from 1B to 27B with text and image input | Google: Introducing Gemma 3 | |
| Command A | Cohere | 2025-03-13 | Yes | 256000 | Text | 2.5 | 10 | 111B parameters, runs on two GPUs; CC-BY-NC weights | Cohere docs: Command A |
| Gemini 2.5 Pro | 2025-03-25 | No | 1048576 | Text, Image, Audio, Video, PDF | 1.25 | 10 | Thinking model released as experimental; paid preview pricing from April 4, 2025 ($1.25/$10 for prompts up to 200K tokens) | Google: Gemini 2.5, our most intelligent AI model | |
| Llama 4 Maverick | Meta | 2025-04-05 | Yes | 1000000 | Text, Image | — | — | 17B active, 400B total parameters, 128 experts; natively multimodal. | The Llama 4 herd (Meta AI) |
| Llama 4 Scout | Meta | 2025-04-05 | Yes | 10000000 | Text, Image | — | — | First Llama mixture-of-experts models (17B active, 109B total); Meta called its 10M-token context industry-leading. | The Llama 4 herd (Meta AI) |
| GPT-4.1 | OpenAI | 2025-04-14 | No | 1047576 | Text, Image | 2 | 8 | First OpenAI models with a 1M-token context window (with GPT-4.1 mini and nano) | OpenAI API changelog (Apr 14, 2025) |
| o3 | OpenAI | 2025-04-16 | No | 200000 | Text, Image | 10 | 40 | Released with o4-mini; price cut 80% to $2/$8 on 2025-06-10 | OpenAI API changelog (Apr 16, 2025) |
| Qwen3 (Qwen3-235B-A22B) | Alibaba Qwen | 2025-04-29 | Yes | 128000 | Text | — | — | Hybrid thinking/non-thinking family; flagship MoE has 235B total and 22B active parameters; Apache 2.0. | Qwen3: Think Deeper, Act Faster (Qwen blog) |
| Amazon Nova Premier | Amazon | 2025-04-30 | No | 1000000 | Text, Image, Video | — | — | Amazon's most capable Nova 1 model and a teacher for model distillation | AWS News Blog: Amazon Nova Premier |
| Mistral Medium 3 | Mistral AI | 2025-05-07 | No | — | Text, Image | 0.4 | 2 | Closed model Mistral pitched at 90% of Claude Sonnet 3.7's benchmark scores for lower cost. | Medium is the new large (Mistral AI) |
| Claude Opus 4 | Anthropic | 2025-05-22 | No | — | Text, Image | 15 | 75 | Claude 4 launch with Sonnet 4 ($3/$15); Claude Code became generally available | Anthropic: Introducing Claude 4 |
| Claude Sonnet 4 | Anthropic | 2025-05-22 | No | — | Text, Image | 3 | 15 | Released alongside Opus 4; available to free claude.ai users | Anthropic: Introducing Claude 4 |
| ERNIE 4.5 (ERNIE-4.5-300B-A47B) | Baidu | 2025-06 | Yes | 131072 | Text | — | — | Baidu's first open-weight ERNIE family (ten variants up to 424B total parameters), Apache 2.0; rollout began June 29-30, 2025. | China's Baidu open-sources its Ernie AI model (SiliconANGLE) |
| Magistral Small / Medium | Mistral AI | 2025-06-10 | Yes | 128000 | Text | — | — | Mistral's first reasoning models; Small (24B) open under Apache 2.0, Medium closed. Context figure is for Small. | Magistral (Mistral AI) |
| MiniMax-M1 | MiniMax | 2025-06-16 | Yes | 1000000 | Text | 0.4 | 2.2 | Hybrid-attention reasoning model (456B total, 45.9B active) with a 1M-token context; price shown is for inputs up to 200K tokens. Apache 2.0. | MiniMax-M1 announcement (MiniMax news) |
| Grok 4 | xAI | 2025-07-09 | No | 256000 | Text, Image | — | — | Native tool use and real-time search; API context 256,000 tokens. | Grok 4 (xAI) |
| Kimi K2 | Moonshot AI | 2025-07-11 | Yes | 128000 | Text | — | — | MoE with 1T total and 32B active parameters, trained with the Muon optimizer; modified MIT license. | Kimi K2: Open Agentic Intelligence (Moonshot AI) |
| GLM-4.5 | Z.ai (Zhipu) | 2025-07-28 | Yes | 128000 | Text | — | — | MoE with 355B total and 32B active parameters (Air: 106B/12B), MIT license. | GLM-4.5: Reasoning, Coding, and Agentic Abilities (Z.ai blog) |
| Grok 2 (open weights) | xAI | 2025-08 | Yes | — | Text, Image | — | — | Weights of the 2024 Grok 2 model published under the Grok 2 Community License Agreement. | xai-org/grok-2 (Hugging Face) |
| gpt-oss-120b | OpenAI | 2025-08-05 | Yes | 131072 | Text | — | — | OpenAI's first open-weight language models since GPT-2 (with gpt-oss-20b); Apache 2.0; 117B total, 5.1B active parameters | OpenAI: Introducing gpt-oss |
| GPT-5 | OpenAI | 2025-08-07 | No | 400000 | Text, Image | 1.25 | 10 | Released in three sizes (gpt-5, mini, nano); 272K input plus 128K output tokens | OpenAI: Introducing GPT-5 for developers |
| Seed-OSS-36B | ByteDance Seed | 2025-08-20 | Yes | 512000 | Text | — | — | 36B dense model trained on 12T tokens with native 512K context, Apache 2.0. | Seed-OSS-36B-Instruct model card (Hugging Face) |
| DeepSeek-V3.1 | DeepSeek | 2025-08-21 | Yes | 128000 | Text | — | — | Single model with switchable thinking and non-thinking modes; MIT license. | DeepSeek-V3.1 Release (DeepSeek API news) |
| MAI-1-preview | Microsoft | 2025-08-28 | No | — | Text | — | — | Microsoft AI's first foundation model trained end to end in-house; public testing on LMArena | Microsoft AI: Two in-house models in support of our mission |
| Qwen3-Max-Preview | Alibaba Qwen | 2025-09-05 | No | 262144 | Text | — | — | Alibaba's first model above 1 trillion parameters; API and Qwen Chat only, no open weights. | Qwen3-Max arrives in preview with 1 trillion parameters (VentureBeat) |
| Claude Sonnet 4.5 | Anthropic | 2025-09-29 | No | 200000 | Text, Image | 3 | 15 | Sonnet upgrade focused on coding and agents | Anthropic: Introducing Claude Sonnet 4.5 |
| Claude Haiku 4.5 | Anthropic | 2025-10-15 | No | 200000 | Text, Image | 1 | 5 | Small model priced at $1/$5 | Anthropic: Introducing Claude Haiku 4.5 |
| MiniMax-M2 | MiniMax | 2025-10-27 | Yes | — | Text | 0.3 | 1.2 | MoE with 230B total and 10B active parameters aimed at coding and agents; modified MIT license. | MiniMax M2 & Agent: Ingenious in Simplicity (MiniMax news) |
| Kimi K2 Thinking | Moonshot AI | 2025-11-06 | Yes | 256000 | Text | — | — | Thinking-agent version of K2 (1T total, 32B active) that reasons while calling tools; modified MIT license. | Introducing Kimi K2 Thinking (Moonshot AI) |
| GPT-5.1 | OpenAI | 2025-11-13 | No | 400000 | Text, Image | 1.25 | 10 | Added a 'none' reasoning setting as the default for faster replies | OpenAI API changelog (Nov 13, 2025) |
| Gemini 3 Pro | 2025-11-18 | No | 1048576 | Text, Image, Audio, Video, PDF | 2 | 12 | First Gemini 3 model, released in preview; price applies to prompts up to 200K tokens | Google: Gemini 3 for developers | |
| Claude Opus 4.5 | Anthropic | 2025-11-24 | No | 200000 | Text, Image | 5 | 25 | Cut Opus pricing from $15/$75 to $5/$25 | Anthropic: Introducing Claude Opus 4.5 |
| DeepSeek-V3.2 | DeepSeek | 2025-12-01 | Yes | 128000 | Text | 0.28 | 0.42 | Successor to V3.2-Exp (2025-09-29), which introduced DeepSeek Sparse Attention; first DeepSeek model to integrate thinking into tool use. MIT license. | DeepSeek-V3.2 Release (DeepSeek API news) |
| Amazon Nova 2 Lite | Amazon | 2025-12-02 | No | 1000000 | Text, Image, Video, PDF | — | — | Reasoning model with three thinking levels; Nova 2 Pro released the same day in preview | AWS News Blog: Introducing Amazon Nova 2 Lite |
| Mistral Large 3 | Mistral AI | 2025-12-02 | Yes | 256000 | Text, Image | 0.5 | 1.5 | 675B total / 41B active mixture-of-experts; Apache 2.0 with image understanding. | Introducing Mistral 3 (Mistral AI) |
| GPT-5.2 | OpenAI | 2025-12-11 | No | 400000 | Text, Image | 1.75 | 14 | Added an xhigh reasoning effort level and compaction | OpenAI API changelog (Dec 11, 2025) |
| Jamba2 | AI21 Labs | 2026-01-08 | Yes | 256000 | Text | — | — | Jamba2 3B and Jamba2 Mini (52B total, 12B active); Apache 2.0 weights | AI21 Labs: Introducing Jamba2 |
| Kimi K2.5 | Moonshot AI | 2026-01-27 | Yes | 256000 | Text, Image, Video | — | — | Natively multimodal K2 continuation (about 15T mixed visual and text tokens); 1T total, 32B active; modified MIT license. | Kimi K2.5: Visual Agentic Intelligence (Moonshot AI) |
| Qwen3.5 (Qwen3.5-397B-A17B) | Alibaba Qwen | 2026-02 | Yes | 262144 | Text, Image, Video | — | — | MoE with 397B total and 17B active parameters; first Qwen open-weight flagship with native vision. Apache 2.0; hosted Qwen3.5-Plus offers 1M context. | Alibaba's Qwen 3.5 397B-A17B (VentureBeat) |
| Claude Opus 4.6 | Anthropic | 2026-02-05 | No | 1000000 | Text, Image | 5 | 25 | First Opus model with a 1M-token context window (in beta at launch) | Anthropic: Claude Opus 4.6 |
| GLM-5 | Z.ai (Zhipu) | 2026-02-12 | Yes | 202752 | Text | — | — | MoE with 744B total and 40B active parameters, adopting DeepSeek Sparse Attention; MIT license. | GLM-5: From Vibe Coding to Agentic Engineering (Z.ai blog) |
| Claude Sonnet 4.6 | Anthropic | 2026-02-17 | No | 1000000 | Text, Image | 3 | 15 | 1M-token context in beta at launch; default model for Free and Pro plans | Anthropic: Introducing Sonnet 4.6 |
| Gemini 3.1 Pro | 2026-02-19 | No | 1048576 | Text, Image, Audio, Video, PDF | 2 | 12 | Released in preview in the Gemini API and Gemini app; price for prompts up to 200K tokens | Google: Gemini 3.1 Pro | |
| GPT-5.4 | OpenAI | 2026-03-05 | No | 1050000 | Text, Image | 2.5 | 15 | First GPT-5 model with a 1M-token context window and built-in computer use | OpenAI API changelog (Mar 5, 2026) |
| Mistral Small 4 | Mistral AI | 2026-03-16 | Yes | 256000 | Text, Image | 0.15 | 0.6 | 119B total / 6.5B active; unifies instruct, reasoning and coding; Apache 2.0. | Introducing Mistral Small 4 (Mistral AI) |
| Gemma 4 | 2026-04-02 | Yes | 256000 | Text, Image, Audio | — | — | Released under the Apache 2.0 license; up to 256K context; audio input on smaller sizes | Google: Gemma 4 | |
| Claude Mythos Preview | Anthropic | 2026-04-07 | No | 1000000 | Text, Image | 25 | 125 | Restricted to Project Glasswing cybersecurity partners; Anthropic does not plan general availability | Anthropic: Project Glasswing |
| Muse Spark | Meta | 2026-04-08 | No | — | Text, Image | — | — | First model from Meta Superintelligence Labs; launched in meta.ai and the Meta AI app, API only in private preview. | Introducing Muse Spark (Meta AI) |
| Claude Opus 4.7 | Anthropic | 2026-04-16 | No | 1000000 | Text, Image | 5 | 25 | Higher-resolution vision; introduced the current Claude tokenizer | Anthropic: Introducing Claude Opus 4.7 |
| DeepSeek-V4-Flash | DeepSeek | 2026-04-24 | Yes | 1000000 | Text | 0.14 | 0.28 | Smaller V4 preview model with 284B total and 13B active parameters, MIT license. | DeepSeek V4 Preview Release (DeepSeek API news) |
| DeepSeek-V4-Pro | DeepSeek | 2026-04-24 | Yes | 1000000 | Text | 1.74 | 3.48 | Preview release; MoE with 1.6T total and 49B active parameters, MIT license. Launched at a 75% discount; general availability 2026-08-13. | DeepSeek V4 Preview Release (DeepSeek API news) |
| GPT-5.5 | OpenAI | 2026-04-24 | No | 1050000 | Text, Image | 5 | 30 | Released with GPT-5.5 Pro for harder problems | OpenAI API changelog (Apr 24, 2026) |
| Mistral Medium 3.5 | Mistral AI | 2026-04-28 | Yes | 256000 | Text, Image | 1.5 | 7.5 | Dense 128B model merging instruct, reasoning and coding; modified MIT license. | Mistral changelog (Mistral AI docs) |
| Command A+ | Cohere | 2026-05-20 | Yes | 128000 | Text, Image | — | — | Cohere's first mixture-of-experts model (218B total, 25B active); Apache 2.0 license | Cohere changelog: Announcing Command A+ |
| Claude Opus 4.8 | Anthropic | 2026-05-28 | No | 1000000 | Text, Image | 5 | 25 | Fast mode priced at $10/$50 | Anthropic: Introducing Claude Opus 4.8 |
| MiniMax-M3 | MiniMax | 2026-06-01 | Yes | 1000000 | Text, Image, Video | — | — | Native multimodal MoE (about 428B total, 23B active) with MiniMax Sparse Attention; weights followed within about 10 days under the MiniMax Community License. | MiniMax M3: Frontier Coding, 1M Context, Native Multimodality (MiniMax) |
| Nemotron 3 Ultra | NVIDIA | 2026-06-04 | Yes | 1000000 | Text | — | — | 550B total / 55B active hybrid Mamba-Transformer mixture-of-experts; OpenMDW-1.1 license. | NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16 model card (Hugging Face) |
| Claude Fable 5 | Anthropic | 2026-06-09 | No | 1000000 | Text, Image | 10 | 50 | New tier above Opus; Claude Mythos 5, released the same day, is offered only through a trusted access program | Anthropic: Claude Fable 5 and Claude Mythos 5 |
| GLM-5.2 | Z.ai (Zhipu) | 2026-06-16 | Yes | 1000000 | Text | — | — | Long-horizon model with a 1M-token context, MIT license. | GLM-5.2: Built for Long-Horizon Tasks (Z.ai blog) |
| Claude Sonnet 5 | Anthropic | 2026-06-30 | No | 1000000 | Text, Image | 2 | 10 | Launched at $2/$10 introductory pricing, later made the standard price | Anthropic: Introducing Claude Sonnet 5 |
| GPT-5.6 Sol | OpenAI | 2026-07-09 | No | 1050000 | Text, Image | 4 | 20 | Flagship of the GPT-5.6 family, released with GPT-5.6 Terra ($2/$12) and Luna ($0.20/$1.20) | OpenAI API changelog (Jul 9, 2026) |
| Inkling | Thinking Machines Lab | 2026-07-15 | Yes | 1000000 | Text, Image, Audio | — | — | Thinking Machines' first model; 975B total / 41B active mixture-of-experts; Apache 2.0. | Inkling: Our Open-Weights Model (Thinking Machines Lab) |
| Kimi K3 | Moonshot AI | 2026-07-16 | Yes | 1048576 | Text, Image, Video | 3 | 15 | 2.8T-parameter MoE (model card: 104B active) that Moonshot calls the first open 3T-class model; weights promised by 2026-07-27 under the Kimi K3 License. | Kimi K3: Open Frontier Intelligence (Moonshot AI) |
| Grok 4.5 | xAI | 2026-07-16 | No | 500000 | Text, Image | 2 | 6 | Published under the SpaceXSI brand (SpaceX Super Intelligence LLC) on x.ai; aimed at coding, agentic tasks and knowledge work. | Introducing Grok 4.5 (SpaceXSI) |
| Claude Opus 5 | Anthropic | 2026-07-24 | No | 1000000 | Text, Image | 5 | 25 | Anthropic says it comes close to Fable 5 at half the price | Anthropic: Introducing Claude Opus 5 |
| Qwen3.8-Max | Alibaba Qwen | 2026-08-03 | Yes | 1000000 | Text | — | — | MoE with 2.4T total and 95B active parameters; API first, open weights (Qwen3.8-2.4T-A95B, text-only, custom license) followed in August 2026. | Alibaba Unveils Qwen3.8-Max (Alibaba Group) |
| MAI-Thinking-1 | Microsoft | 2026-08-12 | No | 256000 | Text | — | — | Microsoft AI's first reasoning model; announced at Build on 2026-06-02 in private preview, public preview on Microsoft Foundry from 2026-08-12 | Microsoft AI: Introducing MAI-Thinking-1 |
| GLM-5.3 | Z.ai (Zhipu) | 2026-08-18 | Yes | 1048576 | Text | — | — | Same base as GLM-5.2 with stronger coding; moved from MIT to a custom GLM-5.3 license with conditions for large model-as-a-service operators. | Z.ai release notes (New Released) |
| Claude Fable 5.1 | Anthropic | 2026-09-01 | No | 1000000 | Text, Image | 10 | 50 | Same model as Claude Mythos 5.1 with different safeguards; Mythos 5.1 is limited to trusted access programs | Claude Docs: Claude Fable 5.1 overview |
| Gemini 3.8 Flash | 2026-09-02 | No | 1048576 | Text, Image, Audio, Video, PDF | 0.75 | 3.75 | Introductory price through December 31, 2026, rising to $1.50/$7.50 | Google: Gemini 3.8 Flash and 3.8 Flash Cyber | |
| Muse Spark 1.3 | Meta | 2026-09-02 | No | 1000000 | Text, Image, Video, PDF | 1.25 | 4.25 | Available in Muse Code and the Meta Model API; a cheaper contributor tier lets Meta use data to improve products. | Introducing Muse Spark 1.3 (Meta AI Research) |
| GPT-6 Astra | OpenAI | 2026-09-03 | No | 1050000 | Text, Image | 10 | 50 | OpenAI's flagship GPT-6 model; does not support the 'none' reasoning level | OpenAI API changelog (Sep 3, 2026) |
| DeepSeek-V4.1-Flash | DeepSeek | 2026-09-10 | Yes | 1000000 | Text, Image | 0.3 | 1.2 | 552B-parameter MoE with a causal encoder-decoder design (8B active for input, 16B for output) and native vision; MIT license. Prices are peak rates; off-peak is half. | DeepSeek-V4.1-Flash Release (DeepSeek API news) |
| Grok 4.7 | xAI | 2026-09-21 | No | 500000 | Text, Image | 2 | 6 | New, larger base model than Grok 4.6, same price. | Introducing Grok 4.7 (SpaceXSI) |
| Claude Opus 5.5 | Anthropic | 2026-09-22 | No | 1000000 | Text, Image | 4 | 20 | First model in the Claude 5.5 family; prices 20% below Opus 5 | Anthropic: Claude Opus 5.5 |
| GPT-6 Luna | OpenAI | 2026-09-22 | No | 1050000 | Text, Image | 0.1 | 0.5 | Lowest-cost GPT-6 model, for high-volume tasks | OpenAI API changelog (Sep 22, 2026) |
| GPT-6 Sol | OpenAI | 2026-09-22 | No | 1050000 | Text, Image | 2 | 10 | Half the per-token price of GPT-5.6 Sol; replaced by GPT-6.1 Sol a week later | OpenAI API changelog (Sep 22, 2026) |
| MiMo-V2.6-Pro | Xiaomi | 2026-09-22 | Yes | 1000000 | Text, Image, Video, Audio | — | — | MoE with 1.02T total and 42B active parameters; Xiaomi released weights, technical report, RL environments and code under MIT. | Introducing MiMo-V2.6 series (Xiaomi MiMo) |
| Claude Sonnet 5.5 | Anthropic | 2026-09-28 | No | 1000000 | Text, Image | 2 | 10 | Same price as Sonnet 5 with cache reads halved to $0.10 | Anthropic: Claude Sonnet 5.5 |
| GPT-6.1 Sol | OpenAI | 2026-09-29 | No | 1050000 | Text, Image | 2 | 10 | Released at DevDay 2026; same list price as GPT-6 Sol | OpenAI API changelog (Sep 29, 2026) |
| Mistral Large 4 | Mistral AI | 2026-10-06 | No | 1000000 | Text, Image | — | — | 52B active / 1.05T total mixture-of-experts in public preview; Mistral says open weights are coming soon. Model card lists $1.36/$4.18; a 50% launch discount applied for two weeks. | Mistral Large 4 model card (Mistral AI docs) |
| Claude Haiku 5.5 | Anthropic | 2026-10-07 | No | 1000000 | Text, Image | 0.1 | 0.5 | Price shown is for prompts up to 100K tokens; longer prompts cost $0.50/$2.50 | Anthropic: Introducing Claude Haiku 5.5 |
| Muse Wonder | Meta | 2026-10-12 | No | 1000000 | Text, Image | 4 | 20 | Meta's first frontier model, for long-running agents and computer use; available via Meta Model API and Muse Code. | Muse Wonder: A Frontier Model For Personal & Professional AI Agents (Meta AI Research) |
| Gemini 4 Argon | 2026-10-13 | No | 1048576 | Text, Image, Audio, Video, PDF | 2 | 10 | Announced September 30, 2026 for Fairwind Program cyber defenders; GA October 13 at an introductory price through November 30, then $4/$20; context shared by input, thinking and output | Google: Gemini 4 Argon is now available | |
| Muse Spark Open | Meta | 2026-10-15 | Yes | 1000000 | Text, Image, Audio, Video | — | — | 816B total / 42B active; Meta calls it the most capable US open-weight model to date. Muse Model License with limited commercial terms. | Introducing Muse Spark Open (Meta AI Research) |
| Kimi K3.1 Pro | Moonshot AI | 2026-10-24 | No | 1000000 | Text, Image | — | — | Available in Kimi apps and API; Moonshot says full weights will be released by 2026-11-04, so weights were not yet public as of 2026-10-29. | Kimi K3.1 Pro (Moonshot AI) |
| GPT-6.1 Terra | OpenAI | 2026-10-26 | No | 1050000 | Text, Image | 1 | 5 | Mid-priced GPT-6 model for visual reasoning and computer use | OpenAI API changelog (Oct 26, 2026) |
AI model releases per year, by lab
The table below counts the rows in this dataset by lab and calendar year (2026 runs through October 29). It measures what this timeline includes, not every checkpoint a lab has shipped: minor dated snapshots, fine-tunes and most size variants are folded into one row.
| Lab | 2018 | 2019 | 2020 | 2021 | 2022 | 2023 | 2024 | 2025 | 2026 | Total |
|---|---|---|---|---|---|---|---|---|---|---|
| OpenAI | 1 | 1 | 1 | 0 | 1 | 3 | 4 | 8 | 8 | 27 |
| Anthropic | 0 | 0 | 0 | 0 | 0 | 3 | 3 | 6 | 12 | 24 |
| 1 | 1 | 0 | 0 | 0 | 2 | 4 | 3 | 4 | 15 | |
| Meta | 0 | 0 | 0 | 0 | 1 | 3 | 4 | 2 | 4 | 14 |
| xAI | 0 | 0 | 0 | 0 | 0 | 0 | 2 | 3 | 2 | 7 |
| Mistral AI | 0 | 0 | 0 | 0 | 0 | 2 | 4 | 4 | 3 | 13 |
| DeepSeek | 0 | 0 | 0 | 0 | 0 | 0 | 2 | 3 | 3 | 8 |
| Alibaba Qwen | 0 | 0 | 0 | 0 | 0 | 1 | 3 | 3 | 2 | 9 |
| Moonshot AI | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 2 | 3 | 5 |
| Microsoft | 0 | 0 | 0 | 0 | 0 | 1 | 2 | 1 | 1 | 5 |
| Amazon | 0 | 0 | 0 | 0 | 0 | 1 | 1 | 2 | 0 | 4 |
| Other Chinese labs | 0 | 0 | 0 | 0 | 0 | 1 | 1 | 6 | 5 | 13 |
| Other labs (Cohere, AI21, NVIDIA, others) | 0 | 0 | 0 | 1 | 2 | 2 | 5 | 1 | 4 | 15 |
| All rows | 2 | 2 | 1 | 1 | 4 | 19 | 35 | 44 | 51 | 159 |
Two patterns stand out. Release cadence at the largest labs roughly doubled between 2024 and 2026: Anthropic has 12 rows in 2026 against 3 in 2024, and OpenAI moved to new model families every few months (GPT-5.4 in March, GPT-5.5 in April, GPT-5.6 in July and GPT-6 in September 2026). And Chinese labs outside DeepSeek, Qwen and Moonshot (Z.ai, MiniMax, Xiaomi, Baidu, Tencent, ByteDance) went from one row in 2024 to six in 2025, almost all of them open-weight.
How context windows and API prices have changed
Context windows grew about 2,000-fold in eight years. Documented launch figures in the table:
| Date | Model | Context window (tokens) |
|---|---|---|
| 2018-06 | GPT-1 | 512 |
| 2020-06 | GPT-3 | 2,048 |
| 2023-03 | GPT-4 | 8,192 (32,768 for gpt-4-32k) |
| 2023-07 | Claude 2 | 100,000 |
| 2023-11 | GPT-4 Turbo | 128,000 |
| 2023-11 | Claude 2.1 | 200,000 |
| 2024-04 | Gemini 1.5 Pro | 1,000,000 |
| 2025-04 | Llama 4 Scout | 10,000,000 |
| 2026-03 | GPT-5.4 | 1,050,000 |
One million tokens has become the default rather than the exception. No 2023 row reaches 1 million tokens; 2 of 35 rows in 2024 do, 10 of 44 in 2025, and 39 of 51 in 2026. Opus-class Claude models reached 1 million tokens with Claude Opus 4.6 in February 2026, in beta at launch.
Prices for a given capability tier fell sharply, while the top tier did not get cheaper. OpenAI's flagship input price dropped from $30 per million tokens for GPT-4 (March 2023) to $10 for GPT-4 Turbo (November 2023), $5 for GPT-4o (May 2024) and $2 for GPT-6 Sol and GPT-6.1 Sol (September 2026). Small models fell further: GPT-4o mini launched at $0.15 input and $0.60 output in July 2024, and GPT-6 Luna at $0.10 and $0.50 in September 2026. Anthropic's Opus tier went from $15 and $75 (Claude 3 Opus, March 2024) to $5 and $25 (Claude Opus 4.5, November 2025) and $4 and $20 (Claude Opus 5.5, September 2026). OpenAI cut o3's price by 80% on June 10, 2025, less than two months after launch.
At the same time, labs added more expensive tiers above their previous flagships. GPT-4.5 launched at $75 and $150 per million tokens in February 2025, the highest list price in the table. In 2026, GPT-6 Astra ($10 and $50), Claude Fable 5 and 5.1 ($10 and $50) and the restricted Claude Mythos Preview ($25 and $125 for partners) sit above the mainstream price points. Chinese open-weight models are priced lower: DeepSeek-V4-Flash listed at $0.14 and $0.28 per million tokens in April 2026.
Launch list prices are only a partial guide to cost. Reasoning models bill their thinking tokens as output, so the cost of a task depends on how many tokens a model writes, and introductory prices (Gemini 4 Argon, Gemini 3.8 Flash) rise after a set date.
Open weights versus open source
"Open weights" in this table means the trained model parameters can be downloaded and run on your own hardware. It says nothing about the license, the training data or the training code, and those differ widely between models marked "Yes".
- Permissive licenses. Apache 2.0 (Mistral 7B, Mixtral, gpt-oss, Qwen3, Gemma 4) and MIT (DeepSeek-R1 and V4, MiMo-V2.6-Pro, GLM-4.5) allow commercial use and modification with few conditions.
- Custom community licenses. Meta's Llama licenses allow commercial use but require companies whose products had more than 700 million monthly active users to request a separate license from Meta (Llama 3 license). Kimi K3, Qwen3.8-Max, GLM-5.3 and Muse Spark Open also ship under lab-specific licenses with their own conditions.
- Non-commercial or research licenses. OPT-175B, the first LLaMA, Command R, Command R+, Command A, Codestral and Mistral Large 2 published weights for research or non-commercial use only.
Open source is a stricter standard. The Open Source Initiative's Open Source AI Definition 1.0, released in October 2024, requires the model parameters, the complete code used to train and run the system, and enough detail about the training data for a skilled person to build a substantially equivalent system, all under OSI-approved terms. Most open-weight models publish the weights and inference code but not the training data or full training pipeline, so they meet the first condition and not the others. Ai2's OLMo, which released its training data, code, logs and checkpoints alongside the weights, is an example of a fuller release.
For anyone choosing among the best open-weight models, the license column matters as much as benchmark scores: check whether commercial use, fine-tuning, hosting for third parties and use of outputs to train other models are allowed before deploying.
Methodology
Scope: notable large language model releases from 2018 to October 29, 2026, chosen to cover each major lab's main generations (OpenAI, Anthropic, Google, Meta, xAI, Mistral AI, DeepSeek, Alibaba's Qwen team, Moonshot AI, Microsoft, Amazon, Cohere, AI21 Labs and leading Chinese labs) plus influential open-weight releases from EleutherAI, BigScience, TII, Ai2, NVIDIA and Thinking Machines Lab. Image, video and speech-only models are excluded. Minor dated snapshots and most size variants are merged into one row, so per-lab counts measure this dataset, not total output.
Sources: each row cites the lab's own announcement, model card, Hugging Face card, documentation or API changelog, read during compilation on October 29, 2026. Where one field came from a second official page from the same lab (for example a pricing page or model docs page for the context window), that page was also checked. Three rows (Qwen3-Max-Preview, Qwen3.5 and ERNIE 4.5) cite reputable technology press because no dated official English announcement was found. DeepSeek-R1 cites an archived copy of DeepSeek's own news page, because the live URL now redirects. Wikipedia and third-party trackers were not used as sources.
Release date is the first day the model was publicly usable: in a consumer app, through an API (including public previews), or as downloadable weights. Where a model was announced earlier for limited testing, the note says so (for example, Gemini 1.5 Pro was announced February 15, 2024, and Gemini 4 Argon on September 30, 2026, to a restricted program). Dates shown as YYYY-MM have a documented month but no single documented day.
Prices are the standard list price per million tokens on the lab's own API at launch, before caching, batch or off-peak discounts. Prices quoted per 1,000 tokens in older announcements were multiplied by 1,000. Where a lab launched with an introductory price (Gemini 4 Argon, Gemini 3.8 Flash, Claude Sonnet 5), the introductory price is shown and the note says so. Tiered prices show the lowest tier (for example, Claude Haiku 5.5 for prompts up to 100,000 tokens and Gemini 3 Pro up to 200,000). For a few recent OpenAI and Google models, the price comes from the current pricing page and the changelog records no change since launch. DeepSeek-V3 launched at promotional V2 rates; the row shows its standard price, which took effect February 8, 2025. Prices in Chinese yuan only were left blank rather than converted.
Values not stated by an official source are left blank, never estimated: this includes several Anthropic context windows from 2023 to 2025, most Amazon Nova prices and many open-weight models' prices because their labs offered no API at launch. Context windows are the documented launch maximum, so later extensions are not shown. Counts in the text are computed from the rows in this table. xAI's 2026 announcements appear under the SpaceXSI brand on x.ai; the rows keep the label xAI for continuity.
Cite and Reuse This Dataset
The data is free to reuse under CC BY 4.0: copy it, chart it or build on it, with a link back to this page. Download the CSV or JSON.
Citation
agitracker.io (2026). AI Model Release Timeline: Every Major LLM From GPT-1 to GPT-6 (2018-2026). Updated October 29, 2026. https://agitracker.io/data/ai-model-release-timeline/HTML link
<a href="https://agitracker.io/data/ai-model-release-timeline/">AI Model Release Timeline: Every Major LLM From GPT-1 to GPT-6 (2018-2026)</a> (agitracker.io)Frequently Asked Questions
When was ChatGPT released?
ChatGPT was released on November 30, 2022, as a free research preview, according to OpenAI. It ran on a model from the GPT-3.5 series fine-tuned with reinforcement learning from human feedback. Developers got API access to the same model, gpt-3.5-turbo, on March 1, 2023, at $0.002 per 1,000 tokens. GPT-4 followed on March 14, 2023, and GPT-6 Astra on September 3, 2026.
What is the latest AI model released?
As of October 29, 2026, the most recent releases in this timeline are OpenAI's GPT-6.1 Terra (October 26, 2026), Moonshot AI's Kimi K3.1 Pro (October 24), Meta's Muse Spark Open (October 15), Google's Gemini 4 Argon (generally available October 13) and Meta's Muse Wonder (October 12). New frontier models now arrive every few weeks, so check the release date column for the current order.
What are the best open-weight models?
Among 2026 releases, the largest open-weight models in this table include Moonshot AI's Kimi K3 (2.8 trillion parameters), Alibaba's Qwen3.8-2.4T-A95B, DeepSeek-V4-Pro (1.6 trillion), Xiaomi's MiMo-V2.6-Pro, Thinking Machines' Inkling and Meta's Muse Spark Open. Which is best depends on the task, hardware and license; MiMo-V2.6-Pro and DeepSeek V4 use the permissive MIT license, while Kimi K3 and Qwen3.8 use custom licenses.
What is the difference between open weights and open source AI?
Open-weight models let anyone download the trained parameters, often under licenses that restrict some uses. Open source AI, as defined by the Open Source Initiative in October 2024, also requires the full training and inference code and enough information about the training data to rebuild a substantially equivalent model, all under OSI-approved terms. Most open-weight LLMs, including Llama and many Chinese models, do not meet that full definition.
Which AI model has the largest context window?
In this dataset, Meta's Llama 4 Scout, released April 5, 2025, has the largest documented context window at 10 million tokens. Most 2026 frontier models, including Claude Opus 5.5, GPT-6 Sol, Gemini 4 Argon and DeepSeek V4, offer about 1 million tokens. For comparison, GPT-4 launched in March 2023 with 8,192 tokens, and GPT-1 handled 512.
How many LLMs are there?
There is no fixed count, because labs release new checkpoints, sizes and fine-tunes constantly, and anyone can publish fine-tuned versions of open-weight models. This list of LLMs tracks 159 notable releases from 26 organizations between June 2018 and October 2026, merging minor variants into one row. Of those, 82 shipped with downloadable weights and 77 were available only through apps or APIs.
How have AI model prices changed over time?
Prices for a given tier have fallen steeply. GPT-4 cost $30 per million input tokens in March 2023; GPT-6 Sol cost $2 in September 2026, and GPT-6 Luna $0.10. Anthropic's Opus tier fell from $15 and $75 per million input and output tokens in 2024 to $4 and $20 with Claude Opus 5.5. Labs have also added premium tiers, such as GPT-6 Astra and Claude Fable 5.1 at $10 and $50.
Research Using This Dataset
- AI Release Race: Context Windows Stalled Near 1M Tokens Since 2024: Original analysis of 159 LLM launches: release cadence, a 1M-token context ceiling that has held for 30 months, and launch prices that stopped falling.
- Open Weights Follow Geography: 94% of Chinese Releases vs 29% of US: An analysis of 159 LLM releases finds a lab's headquarters predicts open weights better than release year, and the US-China gap has widened since 2024.
Related Datasets
- Claude system prompt history and every other officially published AI system prompt: An index of officially published system prompts from Anthropic, xAI, OpenAI, Google, Meta, Mistral, Microsoft and Alibaba, with dates, lengths and notable rules.
- Biggest AI companies: most valuable private AI companies by latest valuation: The 45 most valuable private AI companies by latest round, each dated and sourced, plus the top public AI companies by market cap.
- AGI timeline predictions: when experts, surveys and forecasters say AGI will happen: 74 dated, sourced predictions of when AGI, powerful AI or superintelligence will arrive, from CEOs, researchers, expert surveys, Metaculus and the AI 2027 scenario.
Version History
- : First published with 159 records, each linked to its source.
Spotted an error or a missing record? Every row links to its source; corrections are made and dated on this page. See all datasets.